Topview
    • MCP/Skill
    • Plugin
    • API
    • Pricing
    1. Home
    2. Seedance 2 5 Vs Wan 3

    AI Ads

    AI Video AgentAI Ads VideoAI Product VideoAI UGC VideoURL to Video

    AI Avatar

    AI Avatar GeneratorProduct AvatarDesign My AvatarAI Lip Sync

    AI Video

    AI Video GeneratorDrama StudioAI Video Body SwapAI Video UpscalerAI Video Watermark RemoverTikTok Watermark RemoverSora Watermark RemoverSubtitle RemoverAI Motion ControlAI Lip SyncURL to Video

    AI Image

    AI Image GeneratorAI Face SwapAI Image Character SwapAI Image UpscalerAI InpaintAI Image Text EditorPhoto Angle EditorAI RelightingAI Product PhotographyAI Virtual Try-OnAI Storyboard GeneratorExtract Color PaletteImage to Prompt

    AI Voice

    VoiceoverAI Voice CloningAI Music Generator

    3D

    3D World Generator3D Shot Composer

    Use Cases

    AdvertisingAffiliate MarketingEcommerceDTC BrandsAI Live Stream

    Resources

    BlogAffiliate ProgramLearning CenterAlternativeAPI

    Company

    Topview StudioPrivacy PolicyTerms
    Topview

    © 2026 TOPVIEW PTE. LTD.

    Singapore: 20 Collyer Quay #20-03, Singapore 049319
    Los Angeles: 15970 Los Serranos CC Dr #251, Chino Hills, CA 91709

    Seedance 2.5 vs Wan 3

    Which AI video model should you choose?

    Both Seedance 2.5 and Wan 3.0 support AI video workflows up to 30 seconds, with output options reaching 1080p on supported Topview workflows.

    The practical choice comes down to your brief: Seedance 2.5 is worth considering for reference-heavy productions and detailed timing instructions; Wan 3.0 is worth considering when per-second generation cost is a priority.

    Compare the supported settings, existing side-by-side videos, and model-specific trade-offs below before you generate.

    Try Seedance 2.5

    Seedance 2.5

    Up to 30-second clips, up to 50 combined references in the listed Topview workflow, and detailed shot and audio direction.

    Wan 3.0

    Up to 30-second clips, up to 20 combined references in the listed Topview comparison, and lower published per-second reference rates for selected generation modes.

    Limits and prices depend on your mode, account, and selected generation settings. Always review the live generator before submitting a task.

    Seedance 2.5 vs Wan 3.0 — Spec by Spec Comparison

    Both models combine video generation and multimodal direction. The table below distinguishes model-level documentation from settings listed for the Topview workflow.

    DimensionSeedance 2.5Wan 3.0
    DeveloperByteDanceAlibaba
    Main Use CaseLonger, reference-heavy creative briefsMultimodal creation with attention to generation cost
    Duration4s–30s, selectable per second2s–30s, selectable per second
    Resolution480p / 720p / 1080p480p / 720p / 1080p
    Aspect Ratios16:9, 9:16, 3:4, 1:1, 4:3, 21:9 (plus adaptive)16:9, 9:16, 1:1, 4:3, 3:4
    Text to VideoSupportedSupported
    Image to VideoSupportedSupported
    Video & Audio GuidanceSupported in compatible workflowsSupported in compatible workflows
    Image ReferencesUp to 30Up to 10
    Video ReferencesUp to 10Up to 5
    Audio ReferencesUp to 10Up to 5
    Combined ReferencesUp to 50Up to 20
    Audio GenerationAvailable in supported workflowsAvailable in supported workflows
    Timing & Scene DirectionTime-coded instructions and per-second duration selectionShot and scene directions, subject to workflow
    PricingCredits vary by resolution, duration, mode, and plan Eg. 1.5 credits/s for 720pCredits vary by resolution, duration, mode, and plan Eg. 0.5 credits/s for 720p
    Best ForReference-heavy storytelling and detailed creative directionCost-conscious generation and focused creative briefs

    Reference limits reflect the settings currently listed in Topview's comparison, rather than a guarantee across every provider or account. Check the generator for available settings. Plan prices are on the .

    Which Model Should You Choose?

    Start with the type of video you need, not the model name. These recommendations concern workflow fit — not a claim that one model always produces better-looking videos.

    Seedance 2.5 and Wan 3 both support AI video generation up to 30 seconds, but they offer different advantages. Choose Seedance 2.5 for reference-heavy projects, precise timing, and detailed audio direction. Consider Wan 3 for cost-conscious production, longer single-take storytelling, and reference-guided scene creation.

    Choose Seedance 2.5 when you...

    Need to Combine Up to 50 Multimodal References

    Bring complex creative briefs together with up to 50 reference assets: 30 images, 10 videos, and 10 audio files. Guide character identity, product details, motion, environments, and sound within one generation workflow. While Wan 3 only supports 20 references.

    Want to Use Longer Video and Audio References

    Use reference videos and audio files of up to 30.2 seconds each, subject to the workflow's combined-duration limits. Guide movement, pacing, and sound with longer motion takes or music references.

    Need Precise Second-by-Second Video Control

    Choose a video duration from 4 to 30 seconds in one-second increments. Use time-coded instructions to plan shots, actions, transitions, and scene pacing within a continuous video.

    Want to Synchronize Dialogue, Music, and Sound Effects

    Direct dialogue, background music, and sound effects using time-coded instructions. Coordinate speech, action, and atmosphere with native audio generation in a single workflow.

    Choose Wan 3.0 when you...

    Want Lower and More Predictable Generation Costs

    Wan 3.0 lists 0.30 credits/sec at 480p, 0.50 at 720p, and 1.00 at 1080p, compared with 0.70, 1.50, and 3.70 credits/sec for Seedance 2.5 in Topview's published reference pricing. Review the actual credit quote before generating, as rates depend on the selected workflow and plan.

    Need a Continuous Video Shot Up to 30 Seconds

    Create a continuous video sequence up to 30 seconds without stitching together multiple short clips. Ideal for product reveals, uninterrupted camera movements, and brand stories that benefit from a single flowing shot.

    Want to Maintain a Consistent World with Omni Reference

    Use Omni Reference to guide character identity, props, and environments across a longer narrative. Keep your creative world anchored to visual references while developing scenes and actions.

    Need Internet-Search-Assisted Reference-to-Video Creation

    Use internet-search-assisted reference discovery to support video creation with additional visual and contextual material, where this feature is available in your Topview workflow.

    Try Seedance 2.5

    Seedance 2.5 vs Wan 3: Side-by-Side Video Tests

    Same Creative Brief. Two AI Video Models. Nine Real-World Scenarios.

    How do Seedance 2.5 and Wan 3 compare when given the same creative instructions? Explore nine side-by-side video tests covering cinematic VFX, complex action, multimodal references, documentary storytelling, style transitions, dialogue, character interactions, dance synchronization, and literary adaptation.

    Each comparison presents the outputs from both models alongside the original prompt and reference assets where applicable. Watch how each model handles the same creative challenge, examine the details that matter, and explore which model better suits each type of project.

    01. VFX Spectacle — Cinematic Effects and Motion Continuity

    Text to Video · 30s · 16:9

    What We Tested

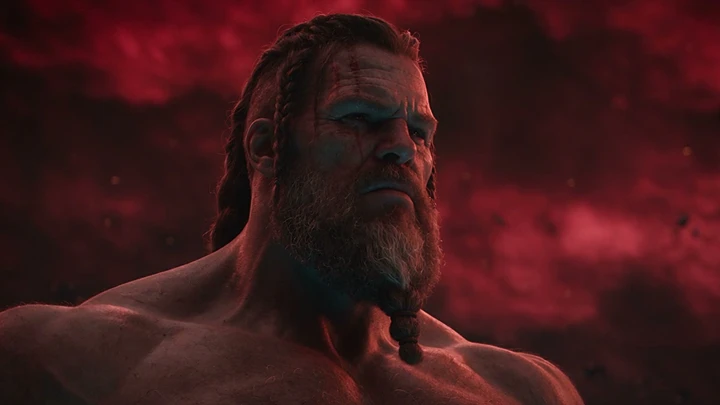
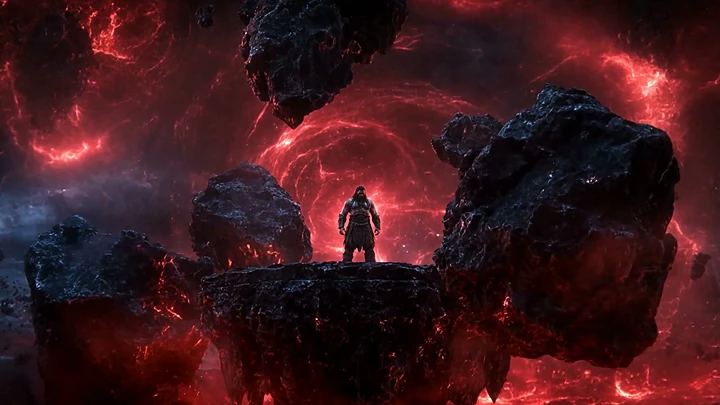
    A Norse god hovers above a fractured obsidian shrine as golden lightning, floating debris, and glowing runes build toward an explosive climax. The camera performs a continuous 360-degree orbit while the character summons a massive battle hammer and releases a powerful shockwave.

    This test challenges both models to combine complex visual effects, character movement, dynamic camera direction, and a continuous action sequence within a single 30-second video.
    Side-by-Side Video Outputs

    Seedance 2.5 — 01. VFX Spectacle — Cinematic Effects and Motion Continuity
    Seedance 2.5
    Wan 3 — 01. VFX Spectacle — Cinematic Effects and Motion Continuity
    Wan 3

    What to Compare

    • Camera Continuity: Does the camera complete the requested 360-degree movement without abrupt jumps or unexpected scene changes?
    • VFX Sequence: Do the lightning, floating debris, hammer formation, and shockwave appear in the intended order?
    • Character Consistency: Does the Norse god maintain a recognizable face, body proportions, and appearance throughout the action?
    • Visual Coherence: Do the effects interact naturally with the character and surrounding environment?

    Why This Test Matters

    Cinematic VFX generation requires more than impressive individual frames. The model must coordinate camera movement, character actions, and visual effects while maintaining a coherent sequence. This test helps reveal how each model handles visually complex scenes with multiple dependent actions.

    Our Verdict

    Seedance 2.5 holds this brief together better. Across the clip, one bearded god stays on one fractured peak: a solemn close-up, the same face with glowing eyes, lightning building on the shrine, then the figure airborne with a hammer. Wan 3.0 makes stronger single effects — a red portal, a debris storm, a gold blast, and a blue rune circle — but the god is missing from the middle of the clip, and the hammer shows up as a pose after the blast rather than a fusion you can follow. The sampled frames do not show a completed 360-degree orbit for either model. Choose Seedance 2.5 when one character and one location have to escalate into the hammer. Choose Wan 3.0 when a spectacular effects shot matters more than staying on the same face and shrine.

    View Full Prompt
    A high-concept mythological action VFX cinematic spectacle shot on Sony Venice 2 with Cine Alta 8K sensor and Leica Summilux-C lenses, featuring photorealistic golden lightning arc flashes, dynamic ray-traced particle physics, floating terrestrial debris, and glowing ancient divine runes illuminated by hyper-detailed volumetric atmosphere. The continuous, seamless 360-degree whip-pan camera begins in a low-angle orbital sweep around a muscular, bearded Norse god suspended in mid-air above a fractured obsidian mountain shrine under a tempestuous crimson sky. His initial solemn and stoic composure dramatically shifts into furious rage as his eyes burst into blinding blue plasma energy, casting vibrant specular highlights across his weathered skin and braided hair. As the camera accelerates its continuous spiral rotation around the god, he lets out a guttural, thunderous roar, raising his right hand to summon violent streaks of celestial lightning that erupt from swirling storm clouds. The raw electrical arcs violently pull floating stone fragments and divine liquid metal together into a swirling vortex, instantly fusing them into a massive, glowing, runic-engraved battle hammer in his fist. Upon gripping the weapon, he detonates a massive radial gravity shockwave that instantly pulverizes the surrounding floating boulders into fine stardust particles and ripples through the thick atmosphere, leaving the ancient fractured shrine beneath him pulsing with deep blue subterranean magic. The unbroken dynamic shot completes its orbital loop to settle into a dramatic wide hero framing of the god hovering amidst the dissipating energy dust, legendary, majestic, thunderous, and escalating from tense stillness to an overwhelming explosive climax.
    1

    02. Game Boss Battle — Complex Action and Spatial Consistency

    Multi Reference · 2 Images · 30s · 16:9

    What We Tested

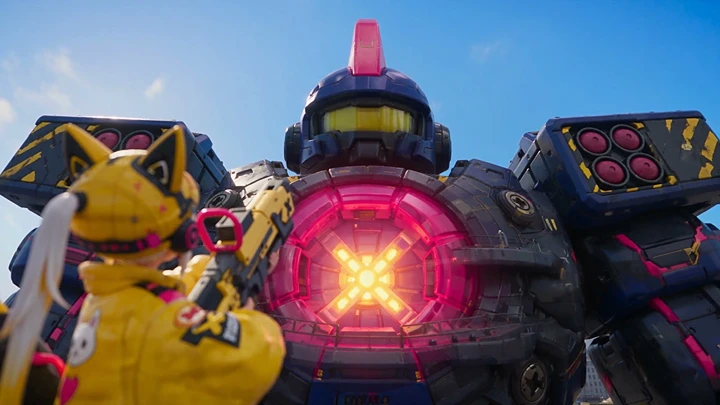
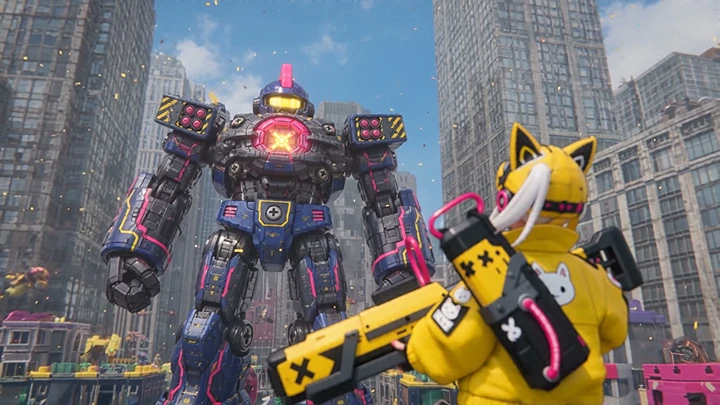
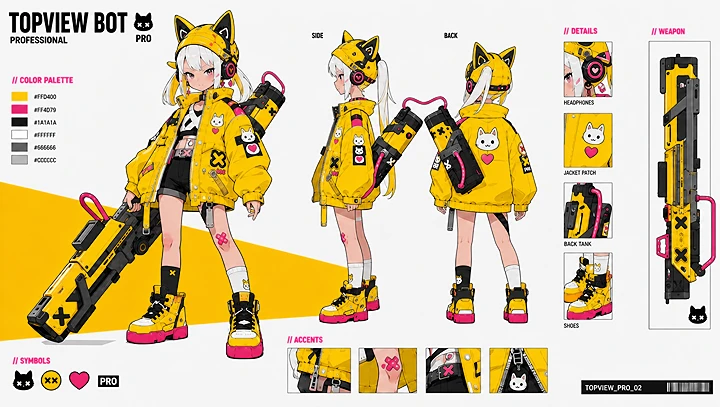
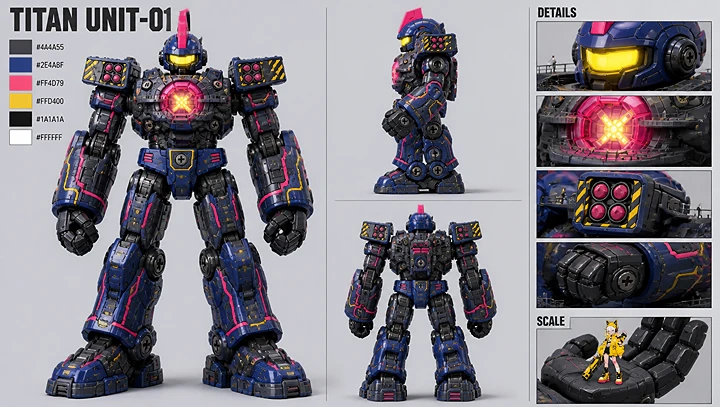
    A small heroine, TOPVIEW BOT, battles a giant toy mech named TITAN in a colorful toy-city environment. Two reference images define the exact appearance of both characters, while the prompt specifies their relative scale, weapon directions, attack sequences, and continuous movement.

    The 30-second battle includes missile attacks, evasive maneuvers, airborne combat, climbing across the mech's armor, and a final energy attack.
    Side-by-Side Video Outputs

    Seedance 2.5 — 02. Game Boss Battle — Complex Action and Spatial Consistency
    Seedance 2.5
    Wan 3 — 02. Game Boss Battle — Complex Action and Spatial Consistency
    Wan 3

    What to Compare

    • Character Reference Fidelity: Do TOPVIEW BOT and TITAN retain the designs shown in their reference images?
    • Scale Consistency: Does the heroine remain significantly smaller than the giant mech throughout the battle?
    • Do movements and combat events follow a coherent sequence without unexpected teleportation or scene resets?

    03. Reference Reasoning — Multi-Image Consistency and World Building

    Multi Reference · 3 Images · 30s · 16:9

    What We Tested

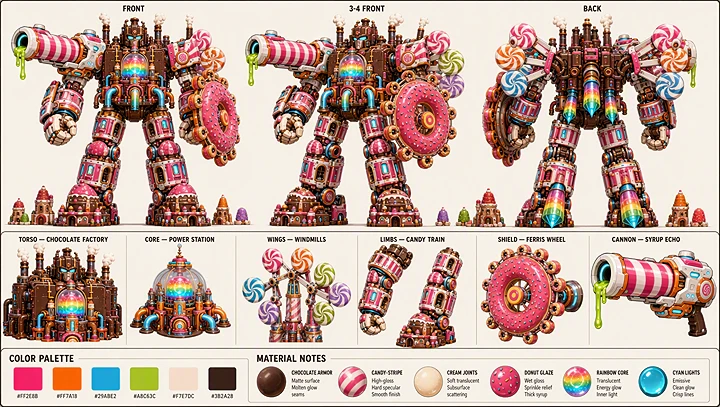
    A colorful Candy Kingdom faces an escalating threat, and the heroine SUGAR POP must defend the city before its landmarks combine into a giant Candy Super Mecha.

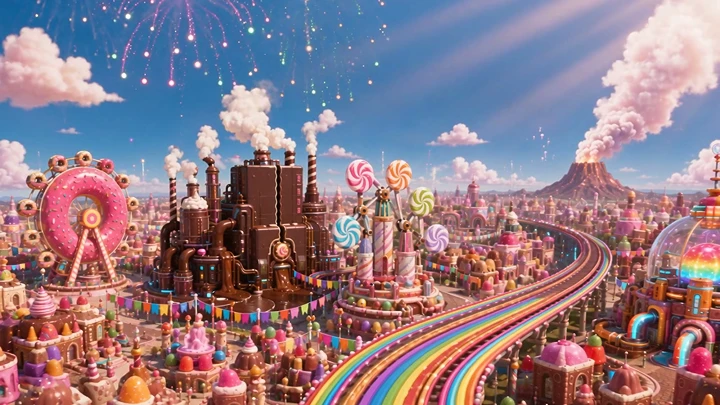
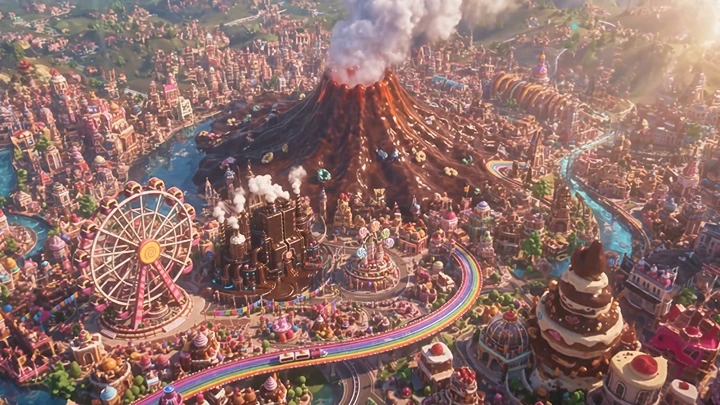
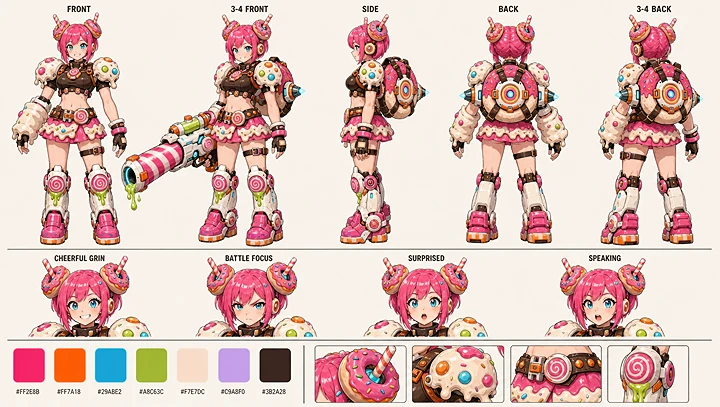
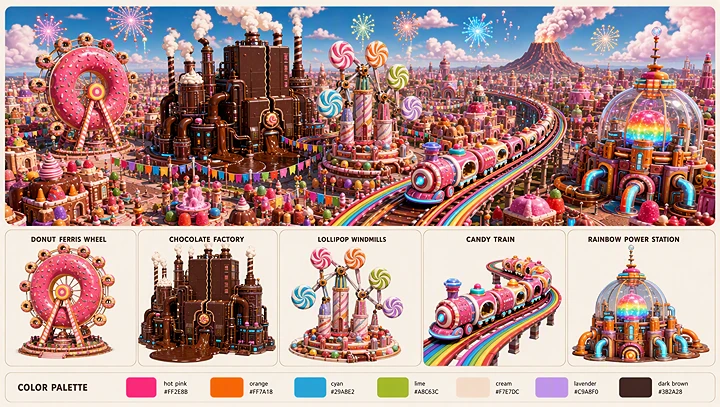
    Three reference sheets define the heroine's appearance, the Candy Kingdom environment and its landmarks, and the final assembled mecha. The prompt requires both models to preserve these designs while generating a complete 30-second action story.
    Side-by-Side Video Outputs

    Seedance 2.5 — 03. Reference Reasoning — Multi-Image Consistency and World Building
    Seedance 2.5
    Wan 3 — 03. Reference Reasoning — Multi-Image Consistency and World Building
    Wan 3

    What to Compare

    • Character Identity: Does SUGAR POP maintain the facial features, hairstyle, outfit, and accessories shown in the reference?
    • Environment Fidelity: Are the Candy Kingdom landmarks recognizable and consistent with the supplied city design?
    • Can the model combine character, environment, and mecha references into one coherent narrative?

    04. Documentary Narration — Storytelling and Audio-Visual Alignment

    Text to Video · 30s · 16:9

    What We Tested

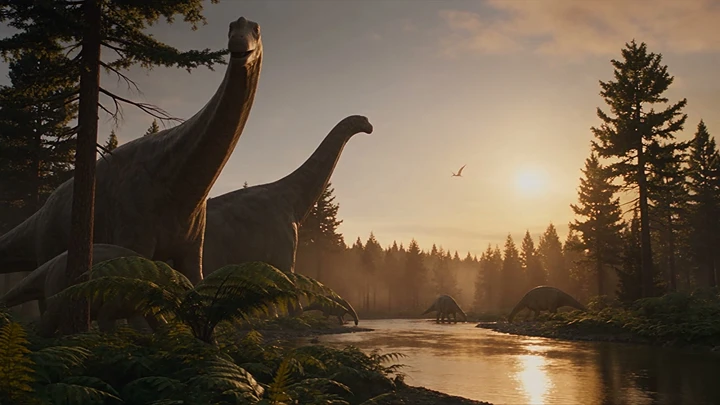
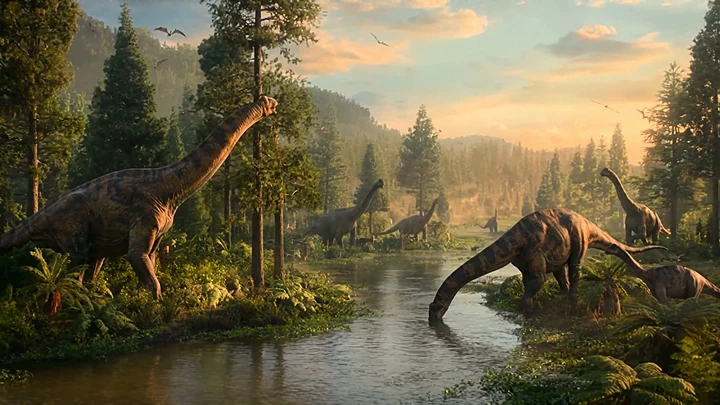
    A natural-history documentary portrays the final moments of a prehistoric ecosystem, moving from a peaceful dinosaur-filled valley to a catastrophic impact, shockwave, volcanic eruptions, and an ash-covered Earth.

    The prompt combines a precisely timed English voice-over with documentary-style cinematography, large-scale environmental events, realistic animal movement, and a quiet orbital ending.
    Side-by-Side Video Outputs

    Seedance 2.5 — 04. Documentary Narration — Storytelling and Audio-Visual Alignment
    Seedance 2.5
    Wan 3 — 04. Documentary Narration — Storytelling and Audio-Visual Alignment
    Wan 3

    What to Compare

    • Narration Accuracy: Does the generated voice-over follow the supplied script with the intended wording, pacing, and pauses?
    • Audio-Visual Synchronization: Do the visuals correspond to the narrated events at the appropriate moments?
    • Does the story move coherently from the peaceful valley to the impact, environmental destruction, and final orbital view?

    05. Style Switching — Visual Transformation and Character Consistency

    Text to Video · 30s · 16:9

    What We Tested

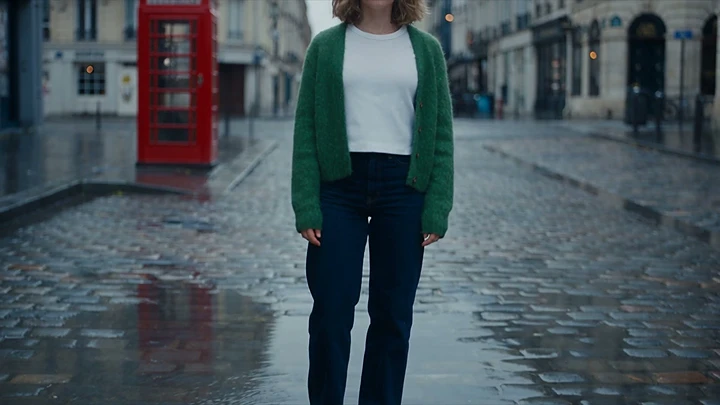
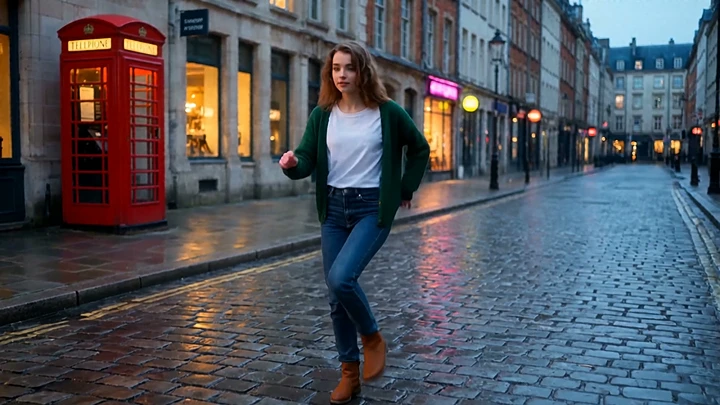
    A female dancer performs one continuous routine while traveling through multiple visual worlds. The video begins in a realistic European street before transitioning into cyberpunk, black-and-white silent film, 3D animation, and oil-painting styles.

    Each transformation changes the visual environment and outfit while the dancer's identity, choreography, and musical rhythm are intended to remain consistent. The sequence ends with all four alternative worlds appearing together in a final composition.
    Side-by-Side Video Outputs

    Seedance 2.5 — 05. Style Switching — Visual Transformation and Character Consistency
    Seedance 2.5
    Wan 3 — 05. Style Switching — Visual Transformation and Character Consistency
    Wan 3

    What to Compare

    • Character Consistency: Does the dancer remain recognizable across different artistic styles and character representations?
    • Style Accuracy: Does each segment clearly reflect the requested visual style without unintended mixing?

    06. Dialogue Scene — Lip Sync and Character Interaction

    Multi Reference · 3 Images · 15s · 16:9

    What We Tested

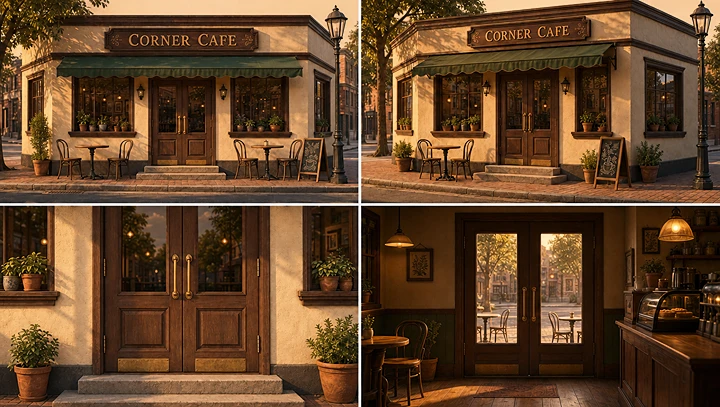
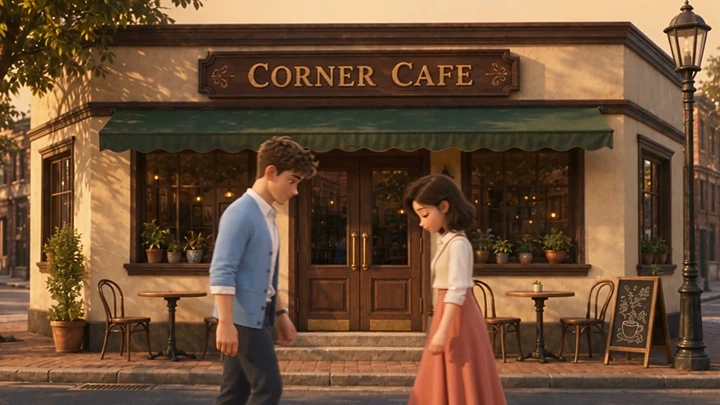
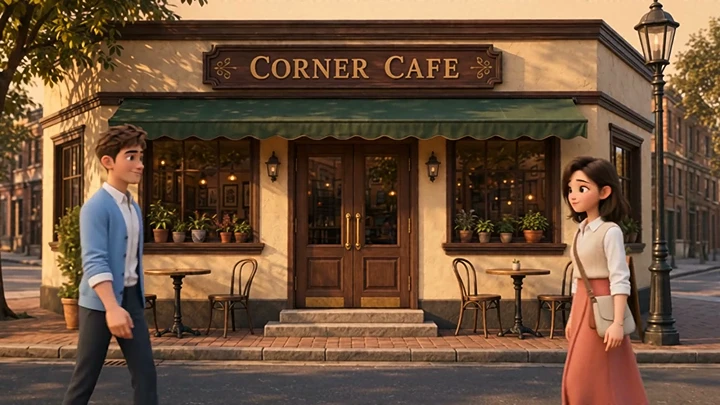
    Two stylized animated characters, HAORAN and XIAOYU, meet unexpectedly outside a café, exchange four lines of English dialogue, and enter the building together.

    Three reference images define the characters and café environment. The prompt requires accurate dialogue, natural facial expressions, consistent character designs, and a specific door-opening action.
    Side-by-Side Video Outputs

    Seedance 2.5 — 06. Dialogue Scene — Lip Sync and Character Interaction
    Seedance 2.5
    Wan 3 — 06. Dialogue Scene — Lip Sync and Character Interaction
    Wan 3

    What to Compare

    • Dialogue Accuracy: Are the specified lines spoken correctly, in the intended order, and by the correct characters?
    • Lip Synchronization: Do mouth movements correspond naturally to the generated speech?
    • Character Consistency: Do HAORAN and XIAOYU retain their referenced facial features, outfits, and animation style?

    07. Ensemble Acting — Multi-Character Coordination and Object Interaction

    Text to Video · 15s · 16:9

    What We Tested

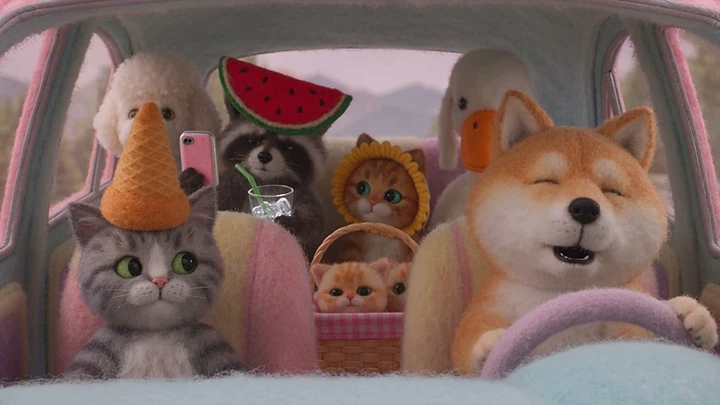
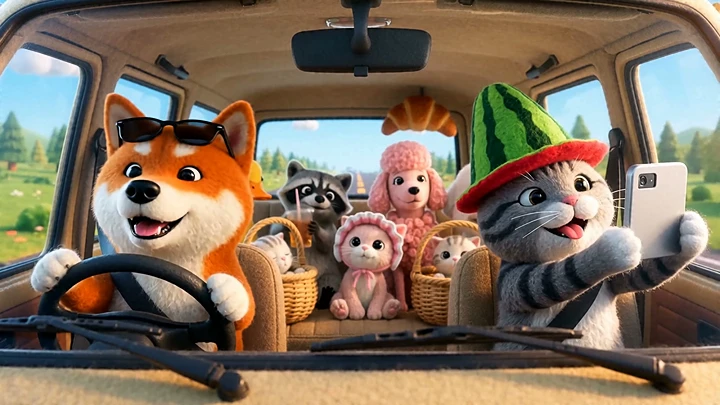
    A group of expressive plush-style animal characters takes a chaotic road trip together. Inside the moving vehicle, each character performs a different action while unexpected events create a chain of comedic reactions.

    The scene includes a singing Shiba Inu driver, a selfie-taking cat, a photobombing duck, shifting hats, bouncing passengers, flying objects, and coordinated group reactions.

    The prompt calls for a fixed camera angle and consistent plush-felt rendering throughout the 15-second sequence.
    Side-by-Side Video Outputs

    Seedance 2.5 — 07. Ensemble Acting — Multi-Character Coordination and Object Interaction
    Seedance 2.5
    Wan 3 — 07. Ensemble Acting — Multi-Character Coordination and Object Interaction
    Wan 3

    What to Compare

    • Character Recognition: Does each animal remain visually distinct and recognizable throughout the scene?
    • Do the characters perform their assigned actions rather than repeating identical movements?

    08. Group Dance & Beat Sync — Choreography and Music Synchronization

    Multi Reference · 1 Image + Audio · 15s · 9:16

    What We Tested

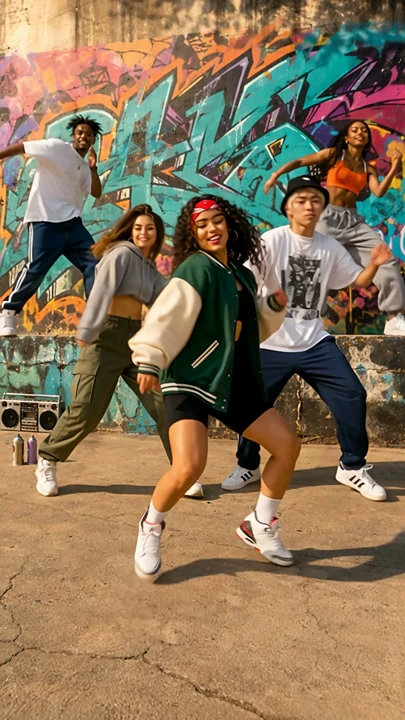
    Five dancers perform a coordinated street-dance routine in a graffiti-covered plaza, using a reference image to define their appearance and an audio reference to guide the choreography.

    The routine begins in a V-formation before transitioning into a horizontal line. The prompt requires all five dancers to preserve their identities, complete the formation change, and synchronize their movements with the original music in one continuous shot.
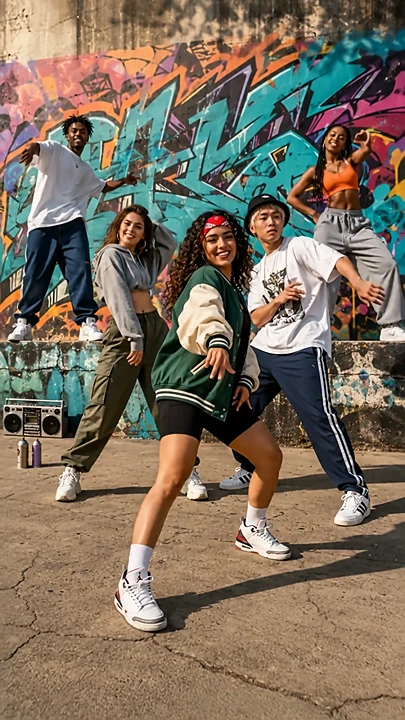
    Side-by-Side Video Outputs

    Seedance 2.5 — 08. Group Dance & Beat Sync — Choreography and Music Synchronization
    Seedance 2.5
    Wan 3 — 08. Group Dance & Beat Sync — Choreography and Music Synchronization
    Wan 3

    What to Compare

    • Beat Synchronization: Do the dancers' movements align with the timing and rhythm of the reference audio?
    • Formation Accuracy: Does the group successfully transition from the starting V-formation to the requested horizontal line?

    09. Literature Adaptation — Narrative Accuracy and Storybook Consistency

    Text to Video · 15s · 16:9

    What We Tested

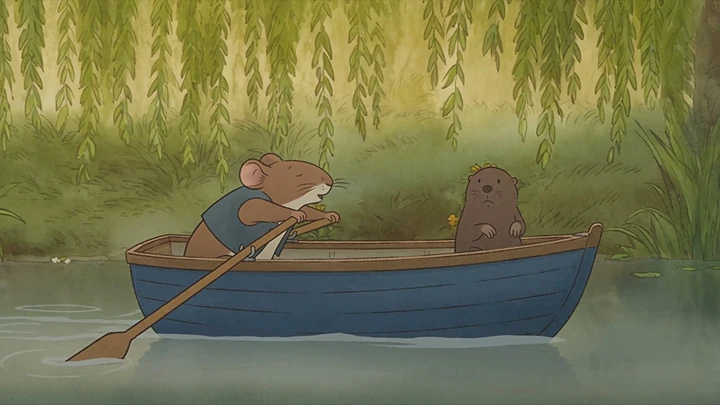
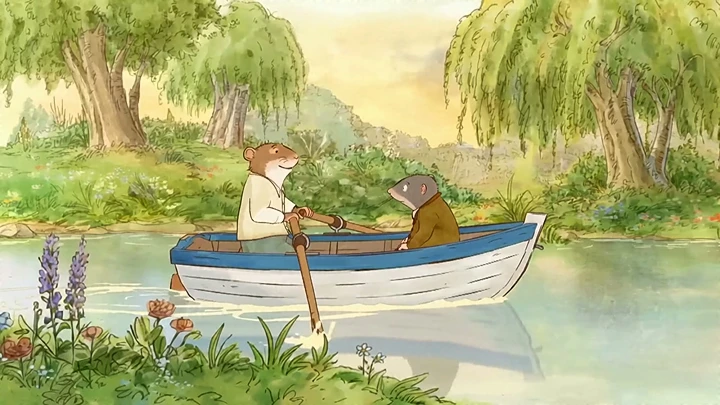
    A short scene from Kenneth Grahame's The Wind in the Willows is adapted into an Edwardian watercolor-style animation.

    A water rat rows a blue-and-white boat along a peaceful river while a mole sits in the stern. As the rat becomes absorbed in conversation, the boat strikes the riverbank, causing the rower to tumble backward before recovering.

    The test challenges both models to reproduce a specific literary sequence while maintaining character roles, physical actions, and a consistent illustrated appearance.
    Side-by-Side Video Outputs

    Seedance 2.5 — 09. Literature Adaptation — Narrative Accuracy and Storybook Consistency
    Seedance 2.5
    Wan 3 — 09. Literature Adaptation — Narrative Accuracy and Storybook Consistency
    Wan 3

    What to Compare

    • Narrative Accuracy: Does the output follow the sequence described in the original passage?
    • Does the rat row the boat while the mole remains in the specified position?

    These nine side-by-side comparisons demonstrate how Seedance 2.5 and Wan 3 respond to specific creative briefs. Results may vary across generations, settings, and reference inputs. Comparative verdicts should be based on the displayed outputs and documented evaluation criteria.

    How We Evaluate Seedance 2.5 vs Wan 3.0

    Our evaluation approach focuses on whether each output solves the original creative task.

    Matching Creative Briefs

    Each comparison uses the same intended prompt and source assets. If a setting is unavailable on one model, that difference should be documented rather than treated as an identical test condition.

    Prompt Adherence

    We check whether the requested subjects, actions, scene order, and endings appear in the output. Missing key events count as limitations even when the video looks polished.

    Reference Consistency

    For image-led cases, we compare characters, products, outfits, props, and locations against their source material. More accurate reproduction is not necessarily the same as more attractive styling.

    Motion and Story Continuity

    We inspect camera paths, body movement, object interactions, and the relationship between successive shots.

    We look for identity drift, abrupt resets, and inconsistent spatial relationships.

    Dialogue, Music, and Sound

    For audio-led cases, we check spoken words, speaker attribution, lip synchronization, sound cues, and beat alignment when the relevant source files are available.

    Generation Reliability

    A reliable performance comparison requires submission records for every attempt, including failed generations, retries, and moderation rejections.

    How Clips Are Selected

    Our planned benchmark uses three generations per model for simpler tasks and five generations per model for more complex tasks, totaling 74 generation attempts across both models.

    Each completed video is evaluated independently using a predefined scoring rubric.

    To avoid cherry-picking visually attractive results, the representative benchmark output is selected based on its proximity to the median blind quality score for that model and scenario.

    Interpreting the Results

    Different models can interpret identical instructions differently.

    One output may excel in composition while another preserves a character or action more closely. The best model for a project is the one that meets the required quality standard at an acceptable cost.

    What Does Generation Cost?

    Compare the same output settings—not just the lowest advertised rate.

    Both models use Topview credits, but actual charges depend on the selected model variant, workflow, duration, resolution, and account plan.

    The generator's credit quote before submission is the most relevant figure for your project.

    Pricing References

    ResolutionSeedance 2.5 on TopviewWan 3.0 on Topview
    480p0.70 credits/sec0.30 credits/sec
    720p1.50 credits/sec0.50 credits/sec
    1080p3.70 credits/sec1.00 credits/sec

    Why the Cheapest Generation Is Not Always the Cheapest Project

    If an output needs multiple attempts before it is usable, the actual production cost includes those attempts.

    Compare total credits consumed, output quality, and the number of acceptable results—not only the advertised per-second price.

    Go Deeper on Each Model

    Seedance 2.5 AI Video Generator

    Explore multimodal references, available video settings, examples, and longer creative workflows.

    Explore Seedance 2.5

    Wan 3.0 AI Video Generator

    Review Wan 3.0 generation modes, supported references, and available settings on Topview.

    Explore Wan 3.0

    Seedance 2.5 API

    Call Seedance 2.5 from the Topview REST API when a product needs video generation in its own workflow. Submit text-to-video, image-to-video, or reference tasks, then poll the async job until the clip is ready. The API page lists Business per-second rates at 480p, 720p, and 1080p.

    Open the Seedance 2.5 API

    Wan 3.0 API

    Call Wan 3.0 from the Topview REST API when generation cost and a published per-second rate matter in your own product. Submit text-to-video or image-to-video tasks, add reference inputs when the live mode accepts them, and poll the async job for the result.

    Open the Wan 3.0 API

    Seedance 2.5 vs Seedance 2.0

    Compare two Seedance versions, their workflows, and existing side-by-side examples.

    Compare Seedance Versions

    How to Use Seedance 2.5

    Follow a beginner-friendly tutorial for choosing a generation mode, writing prompts, and generating a video.

    Read the Tutorial

    Seedance 2.5 vs MiniMax H3

    Compare duration, resolution, references, and native audio, then generate with either model on Topview.

    Compare Seedance 2.5 and MiniMax H3

    Wan 3.0 vs MiniMax H3

    Compare duration, resolution, references, and audio, then generate with either model on Topview.

    Compare Wan 3.0 and MiniMax H3

    Frequently Asked Questions

    The main difference on Topview is workflow emphasis. Seedance 2.5's listed workflow accommodates a larger combined reference set and detailed timing instructions. Wan 3.0 supports multimodal generation and has lower published reference rates in selected pricing schedules. Neither is automatically better for every prompt.

    Not for every task. Seedance 2.5 may be a better starting point for reference-heavy or tightly directed projects. Wan 3.0 may be worth testing when your brief fits its available inputs and generation cost is important. Compare outputs under matching conditions before choosing.

    Both support video generation up to 30 seconds in their documented workflows. Available durations may vary by mode or account. Check the generator before planning a time-critical deliverable.

    Topview's published comparison lists 480p, 720p, and 1080p for both Seedance 2.5 and Wan 3.0. Higher-resolution exports from external upscaling services should not be confused with native generation settings.

    The Topview comparison currently lists up to 50 combined references for Seedance 2.5 and up to 20 for Wan 3.0, with separate limits for images, video, and audio. These are workflow-specific settings. Confirm the limits in your selected generator.

    Both have documented audio-capable workflows. Actual sound options depend on the model, mode, and account settings. Review dialogue, sound effects, and synchronization in the generated result.

    Topview's published reference schedules show lower per-second rates for Wan 3.0 Prime I2V/T2V than the listed Seedance 2.5 Business examples at 480p, 720p, and 1080p. However, these schedules have different plan and workflow qualifications. Always compare the live credit quotes for the same requested video.

    Alibaba Cloud lists file and link inputs among Wan 3.0's model capabilities. That does not mean every Topview workflow accepts documents or webpages. Confirm the input options in your selected generator before relying on them.

    They are existing side-by-side examples showing how both models handle specific creative briefs. Without complete generation logs, they should not be treated as statistically representative rankings. Controlled benchmark conclusions require documented test runs, matching settings, selection rules, and evaluations.

    Topview provides access to supported AI video models within its creation platform. Open the relevant generator, confirm the selected model, and review your available settings and credits before generating.

    Eligible accounts may receive trial credits, but free access does not mean unlimited generation. Available trial settings, model access, export options, and credit requirements are displayed in the current Topview workflow.

    Seedance 2.5 · Wan 3.0

    Open the Model That Matches Your Brief

    Better AI video starts with the right model for the job.

    Choose Seedance 2.5 for reference-heavy direction and detailed creative control, or explore Wan 3.0 when your brief fits its available inputs and you want to compare generation costs.

    Keep your prompt and references consistent, review the outputs, and choose based on the result — not the model name alone.

    Try Seedance 2.5

    Third-party model and brand names are trademarks of their respective owners. Topview provides access to supported AI models through its independent platform and is not the developer of those third-party models.

    Action Continuity:
  1. Spatial Reasoning: Do the characters maintain logical positions, directions, and distances during the fight?
  2. Weapon Accuracy: Do missiles and energy beams originate from the correct weapons and travel toward the intended targets?
  3. Why This Test Matters

    Complex action scenes place heavy demands on AI video generation. The model must maintain consistent characters, understand relative scale, preserve spatial relationships, and coordinate multiple actions over time. This test examines whether visually ambitious combat sequences remain logically understandable.

    Our Verdict

    Wan 3.0 is the better match for the reference sheets in this fight. Its opening keeps the white twin tails, cat-ear cap, yellow jacket, and cannon readable against the navy mech, pink crest, yellow visor, and pink chest core, and a later frame shows missiles in the air before she is back on the armor. Seedance 2.5 wins the scale read in the fist shot, where she is tiny against the hand, but she drops to street level and her face and weapon are hard to check once the camera pulls wide. Seedance ends on a pink blast with the shooter cropped out; Wan ends with her small against the visor. Choose Wan 3.0 when the character sheets and the missile beat have to stay recognizable. Choose Seedance 2.5 when the giant-versus-tiny contrast matters more than a clean reference match.
    View Full Prompt & References

    Reference Assets

    Image Ref 1 — TOPVIEW BOT Character Design
    Image Ref 1 — TOPVIEW BOT Character Design
    Image Ref 2 — TITAN Mech Design
    Image Ref 2 — TITAN Mech Design
    Toy-world giant boss battle CG, 30s, one continuous unbroken take, seamless continuation from the previous shot. No scene reset, no intro, no establishing shot, no pause, no boss defeat pose. Reference inputs: <<<Image1>>> = TOPVIEW BOT, the small agile girl. <<<Image2>>> = TITAN, the giant boss mech. These names always refer to these images. Each image is the sole visual source for its character's design; match exactly, do not redesign; images override any conflicting text. The previous clip governs pose, momentum, lighting and camera state at frame one. First frame continues the previous ending: TOPVIEW BOT already standing on TITAN's chest armor platform, facing its glowing head at close range above a massive toy city; camera, lighting, pose, wind and momentum carry over seamlessly. TOPVIEW BOT lock (all details per <<<Image1>>> ): a human girl — silver-white twin tails, pink X cheek bandage, yellow cat-ear cap (headwear only), bright yellow oversized jacket, yellow-and-black toy cannon with pink handle, pink cable to her back tank. NO tail of any kind. Palette: bright yellow, hot pink, black, white, grey. TITAN lock (all details per <<<Image2>>> ): hundred-meter toy mech, glossy plastic and diecast, navy-and-grey armor, pink mohawk crest, glowing yellow eye visor, glowing pink X chest core, quad-tube pink shoulder missile pods, segmented giant fists. Weapon set, all must appear: HOMING missiles that track TOPVIEW BOT mid-air, giant fist strikes, sustained yellow visor beam, chest-core energy pulse, toy drones from hidden panels. Scale chain (every frame): TOPVIEW BOT is a child-sized human, small enough to stand inside TITAN's palm (as in the reference sheets). TITAN is 100m tall, matching the grey skyscrapers behind. Toy structures reach only TITAN's shins. On TITAN's body she is smaller than a single armor plate; one fingertip is larger than her whole body. Wide frames include a nearby scale reference (armor seam, screw head, debris). She is NEVER building-sized. Energy source rule (entire 30s): every energy effect has exactly one origin. Yellow beams ONLY from TITAN's visor. Pink-yellow blasts ONLY from her cannon muzzle, traveling along her barrel line. No beams from the sky, off-screen, or multiple directions. Aim rule (every shot): shooting is a four-beat sequence rendered in full — she STOPS, PLANTS her feet or braces mid-air, AIMS both-handed until the barrel line from hands to the named target is clearly visible, then FIRES along that line. Never fires while running, never at empty air. Environment: giant toy city battlefield — building blocks, gift boxes, toy trains, Ferris wheels, teddy bears, plastic debris; realistic grey skyscrapers behind, bright blue sky, floating confetti. Spatial continuity (entire 30s): she never leaves TITAN's body or the air around it. When separated, they face EACH OTHER — never the same direction side by side. When she is ON TITAN's body, TITAN tracks her ONLY by turning its head and visor; torso and legs stay planted in one orientation for the entire film, changing only by slow visible rotation, never flipping or snapping. She never turns her back to TITAN; dodges are sideways or sliding, eyes and cannon toward the threat. Every segment starts exactly where the last ended: same position, facing, camera. No teleporting for either character. Timeline (every beat is an exchange; state carries across boundaries): 0–5s | Face-off. Over-the-shoulder staging: camera low behind TOPVIEW BOT — her back and twin tails in the foreground, past her shoulder TITAN's glowing head facing her; her figure tiny on the vast chest armor plain. Muzzle aimed at the yellow visor, barrel line visible, NOT lowered. TITAN's visor flares and locks on; head tilts down toward her, servos grinding, missile hatches snap open. She narrows her stance, muzzle on the visor. Camera: slow push-in past her shoulder toward the visor, one move. End: chest center, facing each other, cannon aimed; camera low behind her shoulder. 5–10s | Salvo and sweep. Homing missiles spiral from the shoulder pods toward her while TITAN's open hand sweeps across its own chest to swat her. She dives sideways, slides flat under the sweeping fingers. As the hand pulls back for a second sweep she springs up, STOPS, plants her feet, aims — barrel line to the open palm — and fires two shots INTO the palm, staggering the hand; missiles blast toy debris around her. Camera: swings with her dive into fast lateral tracking, wide lens, heavy motion blur, the giant hand crossing the foreground; settles for the firing beat, then resumes; no cuts. End: chest edge, facing TITAN's head, missiles airborne behind her. 10–15s | Airborne duel. A near-miss explosion hurls her off TITAN. The missiles curve up after her as one tight cluster; the visor fires a sustained yellow beam tracking her. She spins around the beam and stabilizes at the top of her arc facing TITAN. She hangs one beat: braced mid-air, both hands on the grip, muzzle leveled at the cluster — one straight barrel line — then fires a single full-power blast from her muzzle along that line, detonating the cluster in a chain reaction. Camera: carried by the blast into one continuous 360-degree orbit around her, toy city far below; design locked to <<<Image1>>> through every angle. End: top of her arc, facing TITAN, its forearm already rising toward her; torso unmoved. 15–20s | Arm ride. TITAN raises its forearm before its chest to swat her — she angles her fall and lands ON the raised forearm, facing up-arm toward the head. Torso and legs stay planted; TITAN slowly draws the forearm inward toward its own face, visor tracking her, carrying her closer to its head. Its other fist hammers down onto the forearm; she slides forward under the descending fist, dust blasting up. Toy drones dive at her from both sides — she does NOT shoot them; she weaves between them at full sprint and two drones collide chasing her, tumbling off the arm. The in-drawn arm reaches the shoulder; she leaps onto the shoulder armor. Camera: falls with her onto the arm, stays low behind her run as the arm visibly draws inward, drones whipping past the lens, extreme scale contrast. End: on the shoulder, helmet looming above, TITAN's head turned toward her, torso unmoved. 20–25s | Climb to the strike. She leaps from the shoulder toward the helmet. TITAN overcharges its pink X core — rhythmic pulses race up its body, she times her jumps between pulses; its head thrashes in place, body planted. The overcharge exhausts: pulses stop, the visor dims — her window. She lands on the mohawk crest, plants both feet above the visor, flips the cannon downward and jams the muzzle against the visor's top edge — barrel pointing straight down into TITAN's head, both hands on the grip, cable taut — holding as the cannon charges at her muzzle, the only energy light in frame. Camera: one continuous crane rise around the thrashing TITAN, each pulse pushing the frame wider, settling as pulses die. End: braced on the helmet, muzzle pressed to the dimmed visor, fully charged. 25–30s | Blast and continuation. She pulls the trigger: ONE massive beam fires from her muzzle straight down through the visor — sole origin her cannon, sole direction downward along her barrel. Light bursts outward from INSIDE the helmet seams. TITAN's final act — its near fist rises toward its own helmet to crush her, too late: the helmet cracks and TITAN breaks apart into thousands of toy blocks, every fragment from <<<Image2>>> 's materials and colors, no new parts. She kicks off the collapsing helmet, leaps through the fist's shadow and falling debris — blocks tumbling past many times her size — lands on a tumbling block still moving forward. Camera: pushes in close along her barrel line for the beam, then follows her leap through the debris, same take, cutting during action. No victory pose, no freeze frame. Style: AAA game boss battle trailer, stylized anime-inspired 3D CG, glossy toy materials, Ratchet & Clank + Astro Bot + Hi-Fi Rush feeling; high saturation, cinematic lighting, strong rim light, physical debris simulation, constant motion blur, dynamic camera, 24fps anamorphic widescreen. Audio, three distinct layers: BGM: fast electronic rock, heavy drums, synth brass, toy-box chimes, building throughout; ducks under major attacks; cuts off mid-action. TOPVIEW BOT SFX (bright, high-frequency): plastic footsteps, rising cannon charge whine, sharp discharge pops, chime accents on jumps. TITAN SFX (heavy, low-frequency): servo motors, hydraulic hisses, missile hatch clacks, salvo whooshes, beam hum, sub-bass core pulses, groaning diecast, massive fist thuds with plastic rattle. Environment: explosions with toy-brick scatter, debris rain, drone collision crunches. Negative: static camera, slow pacing, scene reset, character redesign, deviation from <<<Image1>>> or <<<Image2>>> , giant girl, shrunken mech, 180-degree body snap, wrist spinning, beams from the sky, firing while running, cat tail, blue jacket, bunny ears, extra limbs, distorted face, bad hands, subtitles, text, watermark, UI, realistic military weapons, gore, dark desaturated colors, black screen, slow-motion ending.
    2
    Multi-Reference Integration:
  4. Object Transformation: Do the specified landmarks combine into the Candy Super Mecha while preserving the intended component designs?
  5. Story Completion: Does the video progress through the planned conflict, transformation, battle, and ending?
  6. Why This Test Matters

    Multi-reference generation requires a model to understand how separate visual inputs relate to one another. Beyond reproducing individual objects, it must preserve identity, combine design elements, and maintain a consistent creative world across changing scenes.

    This test helps evaluate how reliably each model translates several reference images into a longer, structured video.

    Our Verdict

    Seedance 2.5 is the stronger multi-reference result. Its close-up keeps Sugar Pop's pink bob, blue eyes, and candy hairpieces; the middle of the clip launches separate candy landmarks; and the wide robot matches the mecha sheet, with the striped shoulder cannon, donut forearm shield, and candy limbs in one body. The ending is a colored beam with that robot still in frame. Wan 3.0 opens with the clearer Candy Kingdom — ferris wheel, volcano, and candy streets — and it is the clip that shows the dessert monster over the city. Its later frames stay on a candy train and a blurred robot face, so the assembled mecha never locks together the way the design sheet specifies. Choose Seedance 2.5 when the character, the combination, and the finished mecha all have to survive in one video. Choose Wan 3.0 when the kingdom and the monster need to read first.
    View Full Prompt & References

    Reference Assets

    Image Ref 1 — SUGAR POP Character Sheet
    Image Ref 1 — SUGAR POP Character Sheet
    Image Ref 2 — Candy Kingdom Environment Sheet
    Image Ref 2 — Candy Kingdom Environment Sheet
    Image Ref 3 — Candy Super Mecha Design
    Image Ref 3 — Candy Super Mecha Design
    [REFERENCE IMAGES — visual source of truth] <<<Image1>>> = SUGAR POP character sheet: face, hair, outfit, syrup cannon, donut pack. All heroine appearances match @image1 exactly; it overrides any conflicting text below. <<<Image2>>> = CANDY KINGDOM city sheet: skyline layout and the five landmarks (donut ferris wheel, chocolate factory, lollipop windmills, candy train, rainbow power station). All city views and combining buildings match @image2. <<<Image3>>> = CANDY SUPER MECHA sheet: the assembled 300m mecha. All mecha shots match @image3 exactly — component placement, donut shield on left forearm, syrup cannon on right shoulder. Use reference images for design only — do NOT copy their sheet layouts, labels, or color swatches into any frame. [CHARACTER LOCK — identical in every frame, matching <<<Image1>>> ] One cheerful girl hero, young adult in her early 20s, slim athletic build, bright confident smile. Hair: short glossy hot-pink bob with soft bangs, twin side buns wrapped in candy-ring hairpieces (pink/orange/cyan glaze with sprinkles), two candy-stick antennae angled up, syrup highlights. Face: large cyan-blue eyes, thick lashes, small pink blush marks, pale skin. Outfit: dark brown cropped armor top, bare midriff; oversized cream-frosting shoulder pauldrons with candy gems (pink/orange/cyan/lime); short layered frosting skirt with scalloped drip hem and candy trim; brown studded belt with candy buckles; puffy cream gauntlet on right arm, black fingerless glove on left; black thigh strap; chunky white-pink candy mech leg armor with lollipop-disc knees and glaze drips; hot-pink platform boots with orange candy-stripe soles. Weapon: oversized syrup cannon, pink-white candy-stripe barrel, glossy white/orange sci-fi housing, cyan lights, lime syrup dripping from muzzle — as in @image1. Backpack: donut-shaped pack with pink glaze, yellow-pink center ring, side thrusters, doubles as spinning shield — as in @image1. Palette: hot pink #FF2E8B, orange #FF7A18, cyan #29ABE2, lime #A8C63C, cream #F7E7DC, lavender #C9A8F0, dark brown #3B2A28. Same face, hair, armor, cannon in all shots. No costume change, no lookalike characters. [SHOT SEQUENCE — 30s, continuous escalation] 0-2s: Sweeping crane shot over Candy Kingdom festival matching <<<Image2>>> : donut ferris wheel, gumdrop rooftops, rainbow parade, candy fireworks, warm sunny light. 2-4s: Ground shakes. Whip-pan to syrup volcano erupting; colossal dessert monster of molten chocolate, cake slabs and gnashing candy teeth climbs out, swallowing an ice-cream tower. Monster design consistent for the entire video. 4-6s: Low-angle hero reveal: Sugar Pop (<<<Image1>>> ) boosts in on donut-pack thrusters, lands hard on a lollipop platform, cannon snapping into firing position, cream splash on impact. 6-9s: High-speed chase cam beside her as she sprints and boost-dashes across cotton-candy clouds and rainbow rails, firing rainbow candy shells and jelly missiles; camera rolls with her. 9-11.5s: Tracking past monster flank: she unloads a cream shockwave, glaze exploding across its body, but it absorbs the candy energy, glowing brighter and swelling larger. 11.5-14s: Aerial pull-back: monster towers over skyline, engulfing a chocolate district. Tight close-up of her determined eyes, hard cut. 14-17s: CITY COMBINATION. Rapid montage of the five landmarks from <<<Image2>>> : donut ferris wheel DISC detaches — its A-frame base stays on the ground; chocolate factory splits, lollipop windmills fold, candy train coils, rainbow power station ignites. Buildings launch skyward. 17-20s: Orbiting crane shot: the candy structures lock together in midair, forming the 300m candy super mecha exactly matching <<<Image3>>> ; final piece slams into chest with rainbow flash. 20-22s: Interior beat: she (<<<Image1>>> ) leaps into cockpit, candy controls light up. Wide low angle: mecha eyes ignite cyan, cream fists clench, donut shield spins on left forearm, rainbow thrusters flare — all per @image3. 22-26s: Titan clash. Fast alternating shots: mecha cream-fist uppercut; monster chocolate slam blocked by spinning donut shield; syrup energy cannon charges on right shoulder — mecha stays on-model with <<<Image3>>> throughout. Impacts spray candy shards, rainbow particles and cream fireworks. 26-28.5s: Ultimate attack: mecha crosses arms, chest core blooms, colossal rainbow beam pierces sky and wraps monster completely. Darkness dissolves into color; camera pushes through light. 28.5-30s: Kingdom restored matching <<<Image2>>> , festival resumes, confetti and candy petals falling. Fast push-in to syrup volcano crater in distance: two enormous eyes slowly open in darkness — same eye design as the monster. Cut mid-motion. [STYLE / TECH] Hyper-saturated stylized 3D animation with anime shading, glossy candy subsurface materials, syrup gloss and soft-cream translucency. Blend Super Sentai combining sequences, Gundam mecha weight/paneling, Wreck-It Ralph candy density, Kirby cuteness, Disney lighting. Rainbow bloom, sugar-dust particles, sprinkle debris, glaze splashes, volumetric sunbeams, anamorphic flares, punchy motion blur, brief speed ramps on impacts. 24fps cinematic shutter, 2.39:1 widescreen, crane/drone/handheld chase cameras, camera always moving. Joyful heroic energy, scale escalating every few seconds. [NEGATIVE] static camera, freeze frame, fade to black, slow-motion ending, victory pose ending, character inconsistency, hair/eye color change, costume change, cannon design change, duplicate lookalike girls, mecha deviating from <<<Image3>>> , ferris wheel base attached to the mecha shield, monster design changing mid-video, reference sheet layouts or labels appearing in frame, dark or desaturated grading, horror/grotesque gore, blood, realistic photo style, off-model face, warped hands, extra fingers, text artifacts, watermark, logo overlay, blurry, low detail, dialogue close-ups, idle empty frames. [AUDIO] Uplifting orchestral-electro sentai theme with brass hits, candy chimes, bell layers, huge riser into 17s, mecha servo clanks, gooey syrup splats, deep booms on titan impacts, sparkling twinkle on final beam. No dialogue.
    3
    Scene Progression:
  7. Motion and Scale: Do the dinosaurs, shockwave, volcanic events, and environmental effects maintain believable movement and relative scale?
  8. Documentary Style: Does the footage retain the requested natural lighting, film-grain texture, atmospheric depth, and realistic visual treatment?
  9. Why This Test Matters

    Documentary video generation depends on accurate communication, not just cinematic imagery. Narration, scene timing, visual storytelling, and environmental continuity must work together to communicate a complete sequence.

    This test examines how each model coordinates spoken narration with complex visual events over 30 seconds.

    Our Verdict

    Wan 3.0 carries the picture story further. The frames move from a golden river valley to a head-on stampede under a dust wall, an eruption, a fallen animal in the ash, and a gray Earth in orbit. Seedance 2.5 also goes from the sunlit valley to a running herd, a flood with a small stegosaur, and an ash-gray sauropod, but it is still in the peaceful valley well into the clip, and its last sampled frame is featureless gray rather than orbit. The flood, and the small animal against the landscape, are clearer on Seedance. These frames do not confirm the spoken wording, pacing, or pauses. Choose Wan 3.0 when the video has to reach the collapse and the orbital ending. Choose Seedance 2.5 when the valley and the flood need to stay naturalistic, then check whether your own generation reaches orbit.

    View Full Prompt
    Duration: 30s | Aspect ratio: 16:9 ━━ STYLE & FILM LANGUAGE ━━ [P0] Natural history documentary footage. Muted natural color grade, natural sunlight only. Voice-over narration only — no on-screen speaker, no subtitles, no text anywhere in frame. [P1] Shot on 35mm film with extreme telephoto lenses: visible film grain, lifted blacks, atmospheric haze softening distant layers, heat shimmer above sun-warmed ground, occasional out-of-focus foliage crossing the foreground, subtle handheld drift as if filmed from a concealed hide. [P2] Anamorphic lens characteristics: gentle horizontal flare on the impact flash, oval bokeh in defocused foregrounds. Dust motes drifting through backlit air. ━━ NARRATION (voice-over audio generation) ━━ [P0] Generate an English voice-over narration as the primary audio layer. Voice: deep male documentary narrator, low register, calm gravity. Pacing: slow and measured, unhurried, clear pauses between sentences. [P0] The narration text below is AUDIO CONTENT ONLY — a spoken voice-over. It must NEVER appear as on-screen text, subtitles, captions, or lettering in any frame. [P0] Narration script, timed to the visual segments: [0–6s, over the golden valley] "For a hundred and sixty million years... they ruled the Earth." [6–8s] SILENCE — no narration; only the fireball roar and impact. [8–15s, over the shockwave] "The impact unleashed a shockwave that swallowed the continent at the speed of sound." [15–22s, over the eruptions and floods] "Volcanoes erupted in chains. Floods tore through the valleys, devouring their ancient home." [22–26s, over the ash] "And as the ash swallowed the last light of the sun..." [26–27.5s] SILENCE — no narration; the lone Brachiosaurus collapses. [27.5–30s, over the orbital view] "...an age was over. And the universe — never noticed." [P1] Ambient sound follows the visuals: herd calls, river and insect hum in segment one; roaring dust wall and stampede thunder in segment two; eruptions, fire rain hiss and floodwater in segment three; fading to near-total silence in orbit — only the final narration line over stillness. No music. ━━ PHYSICS & SCALE RULES (apply to all segments) ━━ [P0] Animals move with visible weight: ground tremor on footfalls, slow inertia in long necks and tails, momentum carried through turns. Massive distant objects move with slow parallax. [P1] Every frame contains a scale reference smaller than the main subject: ferns, bird-sized pterosaurs, tree canopies, individual boulders. [P2] Skin behavior under motion: loose hide swaying on flanks, muscle groups shifting under weight-bearing legs, nostril condensation in cooler dawn air. ━━ [0–8s] SEGMENT 1: THE LAST GOLDEN HOUR ━━ [P0] Golden-hour Jurassic river valley. Three adult Brachiosaurus of visibly different sizes at staggered depths: the nearest angled three-quarter toward camera feeding on conifer crowns, a second facing away drinking at the river, a juvenile half-hidden behind foreground ferns. NOT identical individuals, NOT evenly spaced, NOT all in side profile. A distant fireball grows in the sky trailing smoke, then a blinding white impact flash on the horizon. [P1] A few Stegosaurus graze in the hazy midground, partially overlapping each other; small pterosaurs circle the tallest neck like gulls around a ship mast. Long warm shadows stretch across the valley floor; river surface carries broken golden reflections. [P2] The nearest Brachiosaurus tears a branch, needles falling; its throat visibly swallows. When the fireball appears, animals lift heads at different moments — not synchronized — nostrils flaring, the juvenile stepping closer to an adult. The impact flash momentarily whites out the right third of frame and throws hard rim-light on every silhouette. ━━ [8–15s] SEGMENT 2: THE SHOCKWAVE ━━ [P0] The camera sits low in the escape path: mixed dinosaur species charge head-on toward and past the lens at different gaits, bodies overlapping, the nearest blurring as they cross frame — NOT side-passing, NOT parallel to camera. Behind them a sonic dust wall fills two-thirds of frame height, advancing with slow massive parallax. [P1] A ring-shaped shockwave visibly flattens the conifer forest row by row before the dust wall; whole trees cartwheel airborne. Ground debris — branches, gravel, torn fronds — streams past the lens. Pterosaurs scatter overhead faster than the ground animals below. [P2] Individual variation inside the stampede: one Stegosaurus stumbles and recovers, a juvenile weaves between adult legs, panicked eye-whites visible on the nearest animal for two frames as it thunders past. The dust wall's leading edge curls and boils, backlit orange by the burning horizon behind it. ━━ [15–22s] SEGMENT 3: PLANETARY FURY ━━ [P0] Chain-erupting volcanoes hurl lava columns and fire rain across the horizon; flash floods and mudflows tear through the valley, sweeping individual Stegosaurus of different sizes at different depths, some facing camera mid-struggle. Creatures occupy under five percent of frame — tiny against planetary-scale forces. [P1] Layered composition: erupting volcano chain in far background, arcing incandescent bombs and fire rain in midground, churning brown floodwater with uprooted trees in foreground. Steam bursts where lava bombs strike water. [P2] The flood carries a torn conifer crown past the lens close enough to defocus; a struggling Stegosaurus grasps footing on a boulder, loses it, is carried around a bend. Ashfall begins as scattered gray flakes drifting into the top of frame. ━━ [22–30s] SEGMENT 4: THE UNIVERSE NEVER NOTICED ━━ [P0] Ash thickens until color drains from orange to monochrome gray. One lone Brachiosaurus, angled three-quarter toward camera, collapses slowly — front legs buckling first, neck settling last, dust billowing on impact. The camera rises vertically through the ash layer into orbit: Earth a dim gray-veiled sphere against a static, silent starfield. Stars do not move, do not twinkle; nothing reacts. [P1] During the ascent the frame passes through seconds of pure featureless gray inside the ash layer, then breaks abruptly into black clarity — the chaos below replaced by absolute stillness. The gray-shrouded Earth occupies the lower third of the final frame, small, off-center. [P2] Ash flakes settle on the fallen animal's back in close view before the ascent begins; its flank rises and falls once, shallowly, then stops. In orbit, thin sunlight grazes the ash shroud's edge — the only warm tone left, fading. ━━ CAMERA PLAN ━━ [P0] Low-angle wide establishing → static low shot facing the oncoming stampede → handheld chaos → slow continuous vertical pull-out to space. [P1] Segment 1 uses slow lateral drift with telephoto compression; Segment 2 stays locked as subjects grow from distant to frame-filling; Segment 3 handheld with impact shake on eruption beats; Segment 4 decelerating rise, easing to full stillness on the final orbital frame. ━━ AVOID ━━ [P0] Avoid: narration text appearing on screen, subtitles, captions, karaoke-style lyrics, text overlays, identical cloned animals, duplicated individuals, uniform spacing, all animals in side profile, cartoon look, meteor reappearing after impact, moving or twinkling stars, background music. [P1] Avoid: over-saturated colors, HDR bloom, glossy plastic skin, video-game render look, perfectly smooth gimbal glide, default slow-motion, over-sharpened detail, synchronized herd movement, humans, buildings, modern objects.
    4
  10. Transition Timing: Do the visual transformations occur at the specified moments and align with the intended movements?
  11. Motion Continuity: Does the choreography continue naturally between different visual worlds?
  12. Final Composition: Does the ending successfully combine the four distinct styles into the requested multi-panel composition?
  13. Why This Test Matters

    Style switching requires a model to separate visual appearance from subject identity and motion. The environment and artistic treatment may change dramatically, but the underlying character and action must remain understandable.

    This test explores how each model handles coordinated transformations across multiple visual styles within one continuous creative sequence.

    Our Verdict

    Seedance 2.5 covers more of the requested worlds. The samples show the wet European street and green cardigan, a neon cyberpunk outfit, a letterboxed black-and-white silent-film frame, a starry oil-paint turn in a blue gown, then the original look surrounded by four separate panes. Wan 3.0 dances more clearly in the street and cyberpunk sections, and its yellow-dress 3D-animation beat is a full scene rather than a picture inside a pane. The silent-film world does not appear in Wan's samples, and the ending is four separate pictures instead of one poster with the dancer at the center. Choose Seedance 2.5 when the style list and the four-world ending are the point of the brief. Choose Wan 3.0 when readable choreography and the cartoon world matter more than the silent-film segment.

    View Full Prompt
    A 30-second creative dance short film, "The Same Dance in Parallel Worlds": one female lead performs a single uninterrupted dance from start to finish; each time the world switches to a new art style, her outfit changes with it, but the choreography flows on seamlessly — one dance traveling through four parallel worlds. The overall feel combines beat-synced outfit-change transitions with cinematic quality; cuts land crisp, movement stays silky. [CHARACTER LOCK] Female lead: European woman in her mid-20s, light-brown shoulder-length curly hair, medium build. Her facial proportions, hairstyle silhouette, and body shape remain 100% consistent through every switch; her outfit is the ONLY element allowed to change, locked per segment as described below. She is a fictional original character and does not resemble any real person. Only this one female lead appears in the entire film — no doubles or copies of her (except her images inside the panes and the poster). 0-5s: Photorealistic cinematic look. Early morning in an old European city street, wet cobblestones reflecting gray-blue daylight, a red telephone box in the blurred background. She wears a green knit cardigan, white T-shirt, and dark-blue jeans, standing mid-street, tapping a toe to the beat, then easing into the dance — swaying side to side, her arm carving the first arc, a spin with her hair swinging out. Medium shot with a slow push-in, subtle handheld feel. 5-9s: On the instant of that hair-swinging spin, the world switches to cyberpunk — a neon pink-purple rainy night, text-free geometric neon tubes flickering in the rain. Her outfit becomes a silver reflective techwear cropped jacket, black tapered pants, and glowing shoe soles; hairstyle unchanged. The choreography picks up the previous arm arc without a seam, shifting into robotic waves and popping hits, raindrops flinging off her movements as beads of light. The camera orbits her in a small arc. 9-12s: A crouch-and-rise move triggers the next switch — the frame becomes a 1930s black-and-white silent film: the entire image fully black-and-white with no color at all, a 4:3 letterboxed frame, film grain and scratches, a slight hand-cranked stutter. Her outfit becomes a 1920s fringe dress; hairstyle unchanged. Riding the momentum of the rise, her steps flow into a fast Charleston kick sequence, fringe flying with every move, as she laughs a big, soundless laugh. Locked-off camera, mimicking a vintage cine camera. 12-16s: A leap-and-land triggers the switch — the world turns into 3D-animated-feature quality: bright saturated colors, soft volumetric light, a rounded storybook town. She becomes a big-eyed cartoon-proportioned version of herself; her outfit becomes a bright-yellow puffy short dress; hairstyle silhouette unchanged. The landing connects seamlessly into light spinning leaps, a little bird circling her, petals lifting with her skirt. The camera rises and rotates playfully. 16-20s: Her skirt sweeping across the foreground triggers the switch — the frame becomes thick post-impressionist oil paint: a night sky of swirling star-and-moon impasto strokes, streetlight halos in stacked gold. Her silhouette is built from oil strokes; her outfit becomes a deep-blue floor-length gown, its hem spreading like flowing brushwork; hairstyle unchanged. The dance opens into grand sweeping arm arcs and continuous turns, every movement trailing colored brushstroke ribbons in the air. The camera slowly pulls back, strokes streaming with her. 20-25s: The camera keeps pulling back; she returns to photorealistic quality and her original green-cardigan look, still turning at the center of a dark void, never stopping. Around her, four glass-like painted panes float in a fixed 2×2 grid, stationary, each pane distinctly different and never repeating, each freezing her signature pose from that world: the top-left pane holds the cyberpunk world — her in the silver techwear jacket frozen on a popping hit, neon pink-purple rainy night behind; the top-right pane holds the black-and-white silent-film world — the entire pane pure black-and-white with no color, her in the fringe dress frozen mid-Charleston-kick, film grain; the bottom-left pane holds the 3D-animation world — the cartoon-proportioned her in the yellow puffy dress frozen mid-spinning-leap, storybook town; the bottom-right pane holds the oil-paint world — her in the deep-blue gown frozen mid-turn with sweeping arms, swirling star-and-moon night sky. She completes two final turns at the center as light from the four panes falls on her from four directions. 25-30s: The four panes converge and merge into her at once; the light contracts as her spin decelerates to a close, and the frame locks into a poster-style composition — the photorealistic her at center in a curtain-call pose: one hand over her heart, the other extended back and outward, a bowing curtsy with head gently lowered, rim light tracing her silhouette. The background behind her is divided by clean cross-shaped split lines into four quadrants: top-left the cyberpunk neon rainy night, top-right the pure black-and-white film-grain street, bottom-left the bright animated storybook town, bottom-right the swirling impasto oil-paint night sky — each quadrant fully holding its own style with crisp boundaries, no bleeding between them. Freeze frame. Sound design: Ambient layer: 0-5s morning street ambience and the tap of her footwork; at every switch the ambience transforms in sync — rain and electric hum for the cyberpunk section, ambience fully stripped to silence for the silent-film section, light birdsong and rustling petals for the animation section, wind for the oil-paint section; through 20-30s it settles into airy reverb with her breathing and the turn of her steps. Music layer: one dance track runs through the entire film with a beat that never stops — only the instrumentation changes per world: a light electronic beat for the realistic opening, synthwave layers joining in the cyberpunk section, the silent-film section snapping instantly to a lone vintage silent-movie piano (beat unchanged), bright orchestration for the animation section, strings swelling through the oil-paint section, building after 20s to the climax, and one clean resolving chord on the curtain-call freeze; every style switch lands precisely on a downbeat. Voice layer: no dialogue, no narration, no voice-over anywhere in the film. [KEY RESTRICTIONS] The female lead is a fictional original character and must not resemble any real celebrity, dancer, or public figure. No brand logos or trademarks may appear; neon lights render only as geometric tube shapes and must not form any text or letters. No clearly legible text or subtitles anywhere in the film; silent-film intertitle cards are expressed only as decorative graphic frames. [NEGATIVE CONSTRAINTS] Facial drift, altered facial structure, or changes to the hairstyle silhouette; the dance breaking, skipping frames, or moves failing to connect across switches; outfits changing mid-segment (outfits change exactly once, at each style-switch instant); duplicated or repeated content across the four panes; any color appearing inside the black-and-white pane; styles bleeding, mixing, or blurring across quadrant boundaries; extra doubles of her appearing outside the panes and poster imagery; deformed or extra fingers; clipping, flickering, ghosting; watermarks, garbled text; abrupt hard cuts without a physical trigger action.
    5
  14. Facial Performance: Do expressions and gestures match the emotional context of the conversation?
  15. Action Accuracy: Does HAORAN open the correct door outward and allow XIAOYU to enter first, as instructed?
  16. Why This Test Matters

    Dialogue scenes combine several demanding tasks: speech generation, lip synchronization, character consistency, emotional performance, and coordinated physical interaction.

    A convincing result depends on these elements working together. This test helps evaluate how effectively each model handles character-driven storytelling.

    Our Verdict

    Both clips keep the reference designs: the blue cardigan, cream vest, salmon skirt, and the Corner Cafe awning. Mouths are open during the conversation, but still frames cannot confirm the four lines or true lip sync. The door is the visible difference. Wan 3.0's last frame shows him holding the brass handle while she goes through the open doorway. Seedance 2.5 walks the pair to the entrance and inside, without a clear moment of the door held open outward. Choose Wan 3.0 for this brief when the entrance action has to match the prompt. Either model works when the priority is keeping the two characters and the cafe consistent; listen to the lines before locking a take.
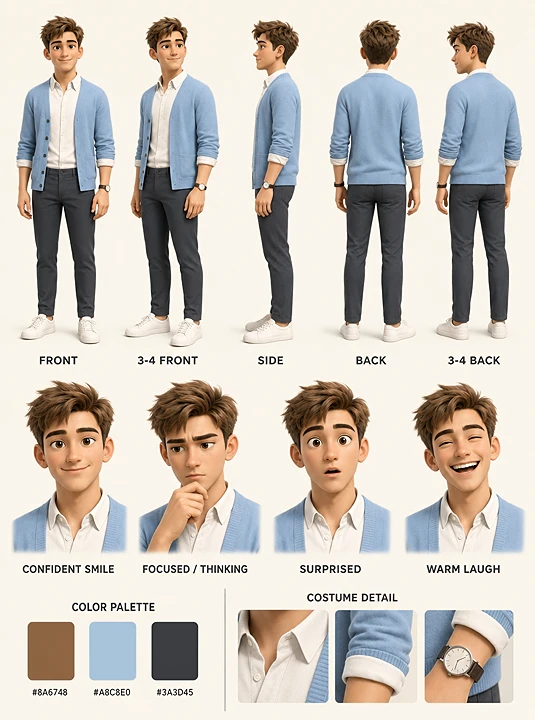
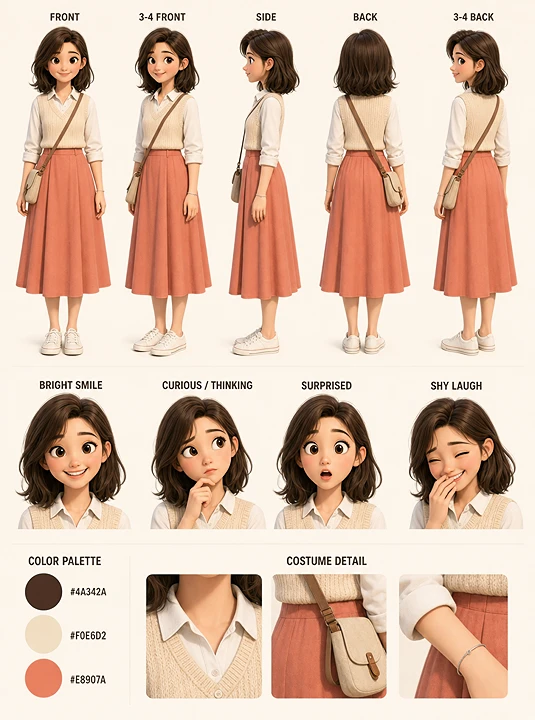
    View Full Prompt & References

    Reference Assets

    Image Ref 1 — HAORAN Character
    Image Ref 1 — HAORAN Character
    Image Ref 2 — XIAOYU Character
    Image Ref 2 — XIAOYU Character
    Image Ref 3 — Café Environment
    Image Ref 3 — Café Environment
    Pixar-style 3D animation, style locked to <<<Image3>>> , <<<Image1>>> and <<<Image2>>> — render everything exactly in their look. HAORAN, the young man from <<<Image1>>> , and XIAOYU, the young woman from <<<Image2>>> , run into each other on the sidewalk in front of the café from <<<Image3>>> , both breaking into surprised, warm smiles. XIAOYU says: "Haoran? What a coincidence!" He laughs: "First time seeing you since graduation!" She replies: "Come on in, coffee's on me." He answers: "Let's go." They walk up the steps together; HAORAN pulls the right door leaf outward by its brass handle — hinges on the outer edge — and holds it open as XIAOYU steps inside, then follows her in as the door swings shut behind them. Soft rounded stylized character proportions, subsurface scattering on skin, large expressive animated eyes, warm golden-hour cinematic lighting, gentle squash-and-stretch motion. The camera tracks them from across the street with a slow push-in. Dialogue in English with accurate lip sync, no subtitles. Avoid photorealistic faces, live-action look, 2D cel-shaded style, any style shift mid-clip, doors opening inward, sliding doors, or extra background characters entering frame.
    6
    Individual Actions:
  17. Object Interactions: Do hats, drinks, grapes, and other objects move between characters in the intended way?
  18. Cause-and-Effect Continuity: Do vehicle turns and bumps trigger coherent reactions across the group?
  19. Scene Consistency: Does the model maintain the fixed camera position, character arrangement, and plush-felt visual style?
  20. Why This Test Matters

    Multi-character acting tests a model's ability to manage several independent actions within a shared environment.

    The challenge is not simply generating many characters at once, but preserving their identities, coordinating their interactions, and maintaining logical cause-and-effect relationships across the scene.

    Our Verdict

    Seedance 2.5 keeps the locked interior. The same windshield view holds the shiba at the wheel with its mouth open, the watermelon-hat cat, and the duck. The duck's neck comes forward, but the hat swap, the grape catch, and the final thumbs-up are not visible. Wan 3.0 shows more of those gags: a croissant on a head, the poodle pressed against the white dog, a grumpy kitten in the basket, and a thumbs-up from the driver. The camera also leaves the locked angle, cutting from the full cabin to the back seat and into the basket, and the hats and seating reshuffle. Choose Seedance 2.5 when one fixed camera and a stable cast matter. Choose Wan 3.0 when the comic chain reaction matters more than a single uninterrupted angle.

    View Full Prompt
    Hyper-realistic wool-felt plush texture, cottagecore pastel palette, matching the reference image exactly. Fixed camera locked at this exact interior angle, no cuts, no camera movement. A hilarious and heartwarming 15-second road trip scene bursting with individual personality. [0-4s] The shiba inu driver is having the time of her life — head bobbing to music, singing loudly with mouth wide open, one paw drumming the steering wheel. The watermelon-hat cat films a selfie video, the duck photobombs by suddenly stretching its neck into frame with a loud honk, the cat rolls its eyes dramatically. The raccoon shakes its iced drink like a cocktail, ice cubes rattling. [4-8s] Sharp left turn! A comedic chain reaction: the croissant hat slides off the grey cat's head and lands on the bonnet kitten's face, covering its eyes — the kitten flails its tiny paws in confusion. The poodle slides across the back seat and squishes the bichon against the window, both bursting into laughter. The duck slides sideways with a deadpan expression, completely unbothered, like it has seen everything. [8-12s] Bumpy road! Everything bounces — a grape pops out of the picnic basket, flies through the air, and the raccoon catches it in its mouth mid-bounce, looking extremely proud of itself. One kitten in the pink basket gets bounced awake, grumpily grabs the edge of the basket, gives everyone an annoyed squint, then dramatically flops back down into the basket. The goldfish leaps out of the sloshing water and splashes back in. [12-15s] The road smooths out into warm golden light. All animals perk up, bright-eyed and alert, turning toward the camera with big open-eyed smiles — the shiba driver glances back with a wide grin and a thumbs-up paw, eyes sparkling; the croissant cat retrieves its hat, puts it on backwards without noticing, and blinks curiously at the camera; the bonnet kitten hiccups a tiny flower petal and giggles with wide shining eyes. Everyone stays awake, lively and energetic, eyes wide open, looking around cheerfully as sunset light glows on their fur. Every animal has exaggerated theatrical acting with natural fur physics — wide eyes, flattened ears, wagging tails, puffed cheeks, dramatic reactions, while rendering stays fully realistic plush-felt style throughout. All characters keep their eyes open and alert throughout, except the basket kittens. Blurred mountain scenery streams past the windows, tree shadows flicker across the interior.
    7
  21. Dancer Consistency: Do all five dancers retain their recognizable faces, hairstyles, and outfits?
  22. Motion Coordination: Do individual movements remain natural and synchronized across the group?
  23. Audio Preservation: Does the generated video retain the original audio without unexpected replacement music or additional sound effects?
  24. Why This Test Matters

    Dance generation requires precise coordination between visual movement, character identity, group positioning, and audio timing.

    A visually appealing dance sequence may still fail if performers lose synchronization or the formation changes incorrectly. This test examines whether each model can coordinate multiple subjects with an external music reference.

    Our Verdict

    Wan 3.0 opens closer to the reference photo: five dancers, the green varsity jacket in front, and a V-like stance against the graffiti wall. Midway, that group disappears and one dancer fills the plaza, before a later frame returns with a looser crowd. Seedance 2.5 keeps a group in every sample, including the green jacket, but later frames add people and do not show a clean change from the starting V into one horizontal line of the same five. Stills cannot confirm that either clip stays on the original beat or leaves the audio untouched. Choose Seedance 2.5 when all of the dancers need to remain in frame. Choose Wan 3.0 when the first shot must match the reference, then watch the middle of the clip before accepting the formation change.
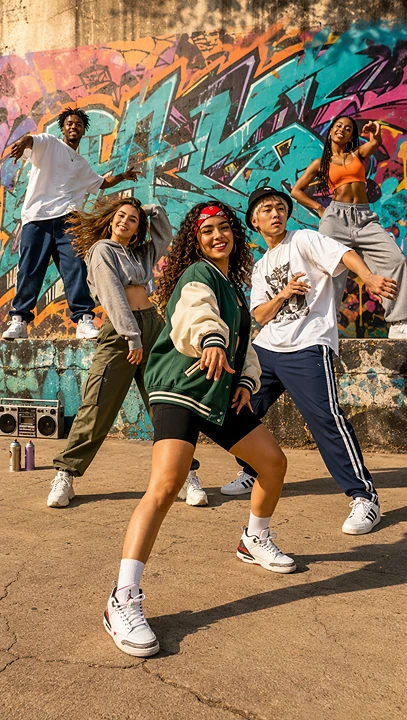
    View Full Prompt & References

    Reference Assets

    Image Ref 1 — Five Dancers and Starting Formation
    Image Ref 1 — Five Dancers and Starting Formation
    Audio Ref — Original Beat Track
    The five dancers from <<<Image1>>> , keeping each dancer's exact face, hairstyle and outfit, perform street dance in the graffiti plaza, choreographed to the music in <<<Audio1>>> , every move landing on the beat. Formation change is required: starting in the V-formation from <<<Image1>>> , midway through the clip all five dancers travel to new positions — the center dancer moves to the back as the other four sweep forward into one horizontal line, finishing the routine in this new formation. Camera movement mirrors the music's rhythm and energy. Continuous single take. Use the ORIGINAL audio from <<<Audio1>>> unchanged; audio reference only, not visual reference. Avoid generated music, added sound effects, cuts, face distortion, identity swapping, subtitles, dancers standing in place for the whole clip.
    8
    Character Roles:
  25. Action Continuity: Does the boat collide with the bank and produce the intended physical reaction?
  26. Visual Style: Does the video maintain the requested Edwardian watercolor aesthetic throughout?
  27. Scene Consistency: Do the boat, riverbank, characters, and surrounding environment remain visually coherent?
  28. Why This Test Matters

    Literary adaptation requires a model to translate written storytelling into a clear visual sequence.

    The challenge is not simply producing attractive storybook imagery. The result should preserve character roles, cause-and-effect relationships, and the essential events that make the original scene recognizable.

    This test helps evaluate how faithfully each model converts a detailed literary passage into a short video.

    Our Verdict

    Seedance 2.5 follows the passage further. The rat rows while the mole sits in the stern, then the rat is on his back with his feet in the air, then he sits up again. The boat reads as solid blue rather than blue outside and white within, and the bow hitting the bank is implied by the fall rather than shown. Wan 3.0 matches the boat better — blue outside, white within — and holds a steadier Edwardian watercolor while they row under the willows. Its late frames tip the boat toward the flowers and then return to calm rowing, so the heels-in-the-air fall and the recovery are missing. Choose Seedance 2.5 when the crash and the tumble have to be readable. Choose Wan 3.0 when the painted boat and the quiet river matter more than the punchline.

    View Full Prompt & Original Passage
    A fifteen-second continuous shot, Edwardian pastoral watercolor style, soft riverside light. A water rat sculls a small rowing boat, painted blue outside and white within, along a gentle river, with a mole seated in the stern, exactly as the original text describes: "Believe me, my young friend, there is nothing—absolute nothing—half so much worth doing as simply messing about in boats. Simply messing," he went on dreamily: "messing—about—in—boats; messing—" "Look ahead, Rat!" cried the Mole suddenly. It was too late. The boat struck the bank full tilt. The dreamer, the joyous oarsman, lay on his back at the bottom of the boat, his heels in the air. "—about in boats—or with boats," the Rat went on composedly, picking himself up with a pleasant laugh." — Kenneth Grahame, The Wind in the Willows (1908), Chapter I, Project Gutenberg #27805 (Scribner 1913 ed.)
    "Believe me, my young friend, there is nothing—absolute nothing—half so much worth doing as simply messing about in boats. Simply messing," he went on dreamily: "messing—about—in—boats; messing—" "Look ahead, Rat!" cried the Mole suddenly. It was too late. The boat struck the bank full tilt. The dreamer, the joyous oarsman, lay on his back at the bottom of the boat, his heels in the air. "—about in boats—or with boats," the Rat went on composedly, picking himself up with a pleasant laugh." — Kenneth Grahame, The Wind in the Willows (1908), Chapter I, Project Gutenberg #27805 (Scribner 1913 ed.)

    Original Source: Kenneth Grahame, The Wind in the Willows (1908), Chapter I. Public-domain text available through Project Gutenberg.

    9
    Topview pricing page